How Amazon Bedrock cuts token costs and latency for JSON AI agents
Executive Briefing
“AWS engineers implemented three composable strategies to cut token consumption by 71...”
Key Takeaways
- 1.The team built a training schedule optimization agent using over 40 tools to verify crew assignments against business rules.
- 2.The three optimization strategies include lightweight session state persistence with heavy artifact offloading to Amazon S3, on-demand result paging for lists, and descriptor-based compaction for oversized dictionaries.
- 3.Across benchmark runs on a representative 23 megabyte payload, these optimizations reduced total token consumption by approximately 71 percent and cut average latency by up to 80 percent.
AWS engineers implemented three composable strategies to cut token consumption by 71 percent and reduce latency by 80 percent for a flight operations agent running on Amazon Bedrock AgentCore. The architecture handles large JSON payloads without bloating the large language model context window.
Key Developments & Primary Facts
The team built a training schedule optimization agent using over 40 tools to verify crew assignments against business rules.
The three optimization strategies include lightweight session state persistence with heavy artifact offloading to Amazon S3, on-demand result paging for lists, and descriptor-based compaction for oversized dictionaries.
Across benchmark runs on a representative 23 megabyte payload, these optimizations reduced total token consumption by approximately 71 percent and cut average latency by up to 80 percent.
Strategic Analysis & Implications
Employing SHA-256 content hashing makes artifact storage idempotent, allowing the system to reuse identical JSON payloads without redundant uploads.
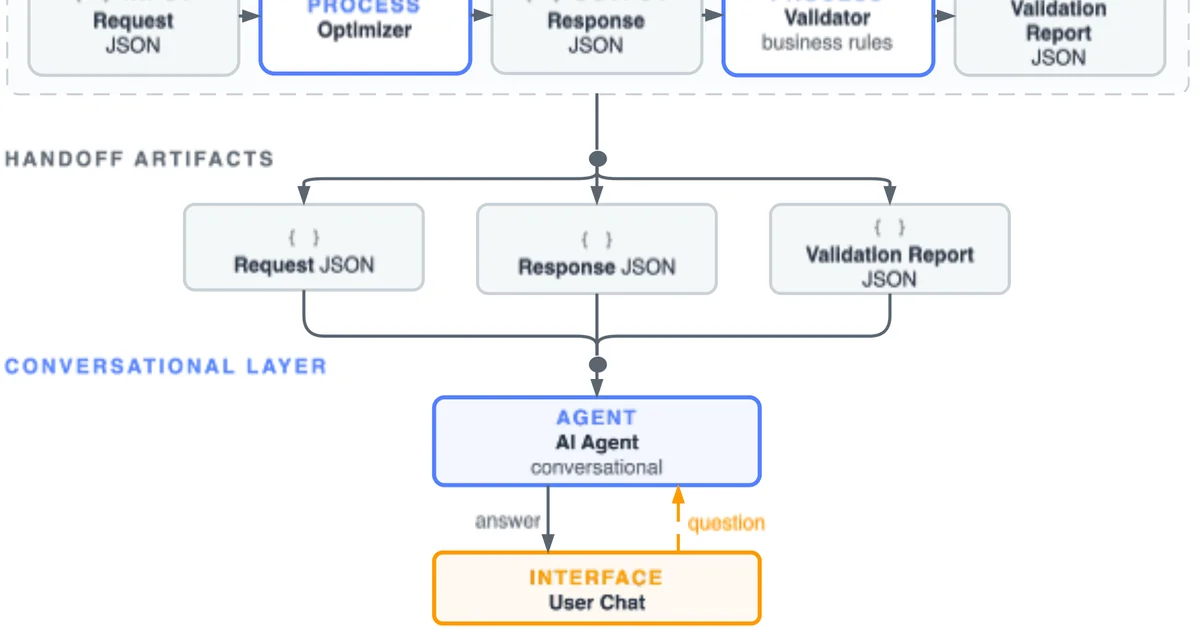
By moving heavy payloads out of conversational context and passing only summaries with handles, the AI agent maintains reasoning capability across extended sessions without context window exhaustion.
Outlook & Factors to Watch
The practical effectiveness of these strategies when applied to large language models outside the Amazon Bedrock ecosystem remains unaddressed in the documentation.
The economic impact of continuous read and write requests to Amazon S3 and cache management overhead has not been detailed.