Four Amazon Bedrock inference choices that affect cost
Executive Briefing
“Inference bills on Amazon Bedrock can continue to climb after prompt tuning due to...”
Key Takeaways
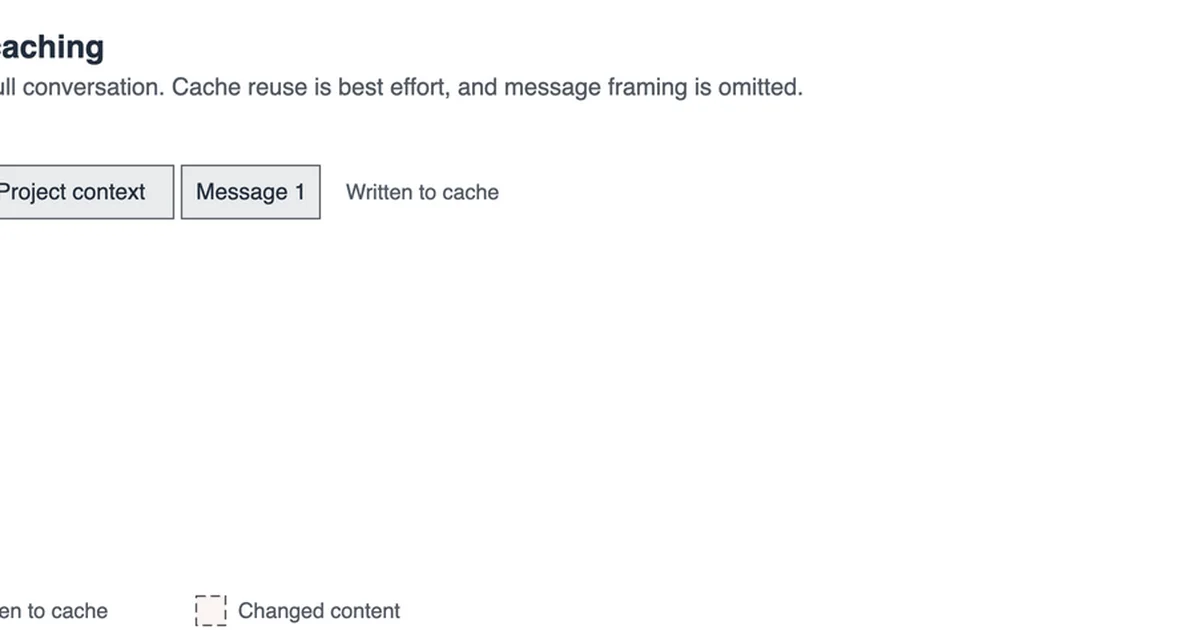
- 1.A 1-hour prompt cache duration requires higher reuse to offset write costs, as a 1-hour write costs twice the input token rate for supported models.
- 2.Selecting the Flex service tier cuts processing costs in half on supported models like Amazon Nova 2 Lite compared to the standard rate, but unsupported models return a validation error.
- 3.Adaptive thinking effort defaults to high on models like Claude Sonnet 5, and lowering the effort level significantly reduces median output tokens depending on the specific task.
Inference bills on Amazon Bedrock can continue to climb after prompt tuning due to request-level choices. Engineers can optimize costs without changing models by adjusting cache duration, service tiers, reasoning effort, and output token limits.
Key Developments and Technical Context
A 1-hour prompt cache duration requires higher reuse to offset write costs, as a 1-hour write costs twice the input token rate for supported models.
Selecting the Flex service tier cuts processing costs in half on supported models like Amazon Nova 2 Lite compared to the standard rate, but unsupported models return a validation error.
Adaptive thinking effort defaults to high on models like Claude Sonnet 5, and lowering the effort level significantly reduces median output tokens depending on the specific task.
Strategic Analysis and Industry Implications
Request-level parameter control gives developers granular command over operational expenses without altering the underlying model architecture. However, engineers must closely monitor task completion rates to ensure token reductions do not degrade output quality.
Optimization strategies such as utilizing the Flex tier or long-duration caching require thorough error handling and tenant partitioning to avoid data boundary risks or disruptions in automated agentic chains.
Outlook and Key Factors to Watch
The actual latency variance of the Flex service tier under complex workloads beyond standard benchmarks remains fully unquantified across all traffic conditions.
The long-term cost-effectiveness of various cache durations when applied to multi-tenant systems with high content volatility requires further empirical validation.