Taxbit Assist: A grounded, role-aware AI agent on Amazon Bedrock AgentCore
Executive Briefing
Synthesized and verified with gemini-2.0-flash-thinking-exp
“Taxbit is a digital-asset tax and accounting compliance platform.”
Key Takeaways
- 1.Taxbit is a digital-asset tax and accounting compliance platform.
- 2.Founded in 2018, Taxbit helps enterprises such as exchanges, payment services, and brokers calculate gains and losses, collect tax documentation, and file information returns at scale.
- 3.Now, a cited, permission-aware AI assistant helps compliance teams find answers right inside the product dashboard.
Taxbit is a digital-asset tax and accounting compliance platform. Founded in 2018, Taxbit helps enterprises such as exchanges, payment services, and brokers calculate gains and losses, collect tax documentation, and file information returns at scale. Now, a cited, permission-aware AI assistant helps compliance teams find answers right inside the product dashboard. But the knowledge needed to use that dashboard well was scattered across the public website, API documentation, and help-center articles, and a meaningful share was never written down at all. When a customer asked “what does this form status mean?”, they either went digging or filed a support ticket. Today more than 55 percent of users who ask Assist a question return to ask another within 24 hours, according to Taxbit’s internal production analytics. In this post, we share how we built Taxbit Assist, the AI assistant now embedded in the Taxbit dashboard, on Amazon Bedrock AgentCore, a platform to build, connect, and optimize agents at scale, with any framework or model. We cover the architecture, the retrieval work that made answers trustworthy enough to ship to regulated customers, how we handle safety and data residency, and how we continuously measure answer quality on live production traffic. What the assistant had to get right A generic chatbot was not an option in this domain. Four constraints shaped what we built:
Grounded and cited – Our users make filing decisions. Every answer had to trace back to a source the user could open and read, and when the assistant didn’t know something, it had to say so. Role and organization awareness – The assistant shouldn’t walk a Support User through an admin-only workflow and send them to a page that they can’t open. No tax advice – Explaining how Taxbit computes cost basis (the accounting method used to compute a gain or loss) is product documentation. Telling a user which method to elect is tax advice. The line between the two is narrow. Regional data residency – Supported from a single codebase, with continuous quality measurement in production. Inside our compliance program – Taxbit Assist is developed and operated in line with ISO/IEC 42001, the international standard for AI management systems. Taxbit is also certified to ISO/IEC 27001 and ISO/IEC 27701 and holds a SOC 2 Type II report. Taxbit doesn’t train or fine-tune any model, and Amazon Bedrock doesn’t use prompts or completions to train models.
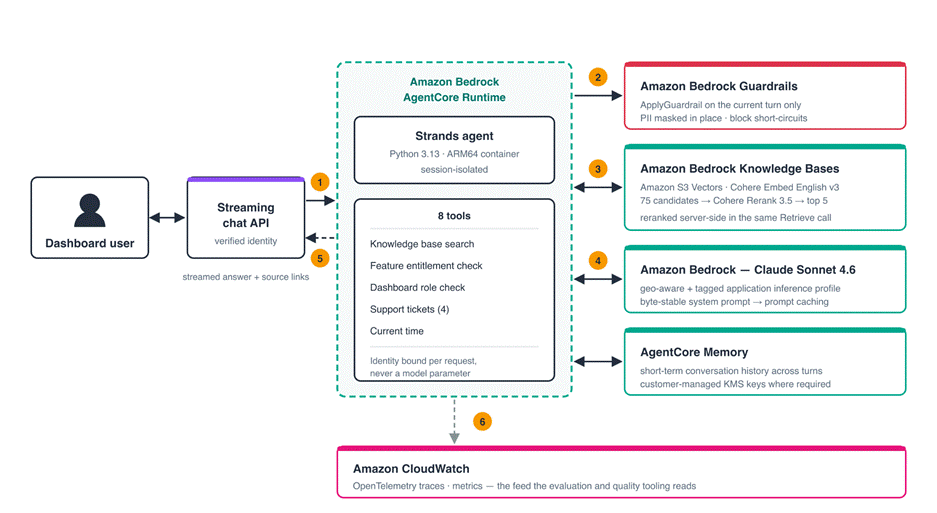
We are also a small team. Rather than build and operate the agent loop, conversation-state store, and session isolation ourselves, we chose Amazon Bedrock AgentCore for three reasons: its managed agent runtime removed infrastructure operations, built-in AgentCore memory, a capability of Amazon Bedrock AgentCore, eliminated a separate conversation-state store, and per-session isolation kept each user’s context contained. That let us put most of our effort into the retrieval and safety work that follows. Solution overview Taxbit Assist is a Strands Agents SDK application running on AgentCore runtime, a capability of Amazon Bedrock AgentCore. The following diagram illustrates the solution architecture.
Figure 1: Request flow from a dashboard question through guardrails screening, knowledge base retrieval, model reasoning, permission checks, and response streaming
The workflow consists of the following steps:
A user asks a question in the Taxbit dashboard. A streaming chat API forwards it to AgentCore runtime along with the user’s verified identity (email, organization ID, and dashboard roles). The runtime screens the incoming message with Amazon Bedrock Guardrails. Personally identifiable information (PII) is masked in place. If the message is blocked, the model is never invoked. The agent retrieves candidate passages from an Amazon Bedrock Knowledge Bases knowledge base, and then reranks them server-side. The knowledge base uses the fully managed Retrieval Augmented Generation (RAG) capability of Amazon Bedrock, backed by Amazon S3 Vectors, a capability of Amazon Simple Storage Service (Amazon S3). Amazon Bedrock models reason over the retrieved passages and verify that the user has access to the relevant feature and role before recommending any workflow. For model availability by AWS Region, see Supported models by AWS Region. The answer streams back to the dashboard with source links. AgentCore memory carries the conversation across turns. Every request emits OpenTelemetry traces to Amazon CloudWatch, which feeds our evaluation tooling.
The agent runtime The agent is a small Python application: a system prompt, a model, and eight tools. It ships as an ARM64 container image that AgentCore runtime pulls from Amazon Elastic Container Registry (Amazon ECR) and scales on demand. The tools are deliberately narrow:
Knowledge base search, the primary tool. Two access checks, one for organization entitlement and one for the user’s dashboard role. Four support ticket tools to create, list, update, and close the caller’s own tickets. Current time, for the rare question that needs sub-day precision.
In this version, the agent has no read access to customer tax data. It answers from product knowledge, and the only writes it can perform are the caller’s own support tickets. One security decision underpins all of them: the model never handles identity. The user’s email, organization ID, and roles come from the trusted calling service and are bound into each tool through a closure before the model sees it. The model can decide whether to check permissions but not whose permissions to check, because identity isn’t a parameter it can set. User input is sanitized at the boundary, so a prompt injection cannot imitate the trusted context line. The agent runs a foundation model (FM) through Amazon Bedrock, invoked through cross-Region inference profiles. Geography-aware inference handles data residency. The inference profile ID carries a geography prefix derived from the deployment Region, so EU deployments keep inference within the EU, and US deployments stay in the US. Beyond keeping inference in the right geography, we also support a bring your own key (BYOK) model. In BYOK accounts, conversation history and the other stores that hold client data are encrypted with the customer’s own AWS Key Management Service (AWS KMS) key. Application inference profiles handle cost visibility. Each deployment wraps the system inference profile in a tagged application profile, so every model invocation carries cost-allocation tags and shows up in AWS Cost Explorer, broken down by workload. Amazon Bedrock prompt caching cuts latency and token cost. The system prompt is byte-identical for every request and ends with a cache checkpoint, so the static prefix is cached across users. Per-request context travels on the user message instead. Grounding answers in a curated knowledge base Most of our engineering effort went into the knowledge base: an Amazon Bedrock knowledge base backed by Amazon S3 Vectors, with Cohere Embed English v3 for embeddings, producing 1,024-dimension float32 vectors compared by cosine distance. All of it is managed, so there is no vector database for us to operate. Ingestion Content flows in from three kinds of sources, each landing under its own prefix in a single Amazon S3 bucket. The following diagram shows how content reaches the index.
Figure 2: Content ingestion pipeline from published, code-derived, and curated sources through Lambda scrapers into Amazon S3 and the knowledge base
Published content comes first: our public website, our API documentation, and our help-center articles, crawled by scheduled AWS Lambda functions. With sitemap lastmod timestamps and content hashes, a typical run only touches what changed since the previous one. Scoping mattered more than we anticipated. Our sitemap has roughly over 400 URLs, but only about over 70 belong in an answer-generating corpus, and /blogs/ alone accounts for more than 300 marketing pages. Left in, that campaign content competes with the help center to become the cited source for compliance questions. Excluding it was one of our highest-value retrieval changes, and it required no model work at all. The second source is less conventional: Lambda functions read our product source code and generate Markdown documentation covering dashboard routes, permission gates, form eligibility logic, and reporting configuration. This captures product truth that exists nowhere else in prose, and it stays current because it’s regenerated from the code itself. The third source is curated content: hand-written articles and approved corrections that fill gaps the automated sources don’t cover. Amazon EventBridge schedules the crawls on a staggered nightly and weekly cadence, and each scraper triggers an ingestion job only when something has changed. We group the nine scrapers into three umbrella data sources split by S3 sub-prefix (product-public/, product-internals/, curated/), which keeps related content together. Contextual chunking We chose semantic chunking, which splits documents at natural boundaries and outperformed fixed-size chunking on our retrieval tests. But a chunk pulled from the middle of a document loses track of what the document is about. In tax reporting, that context is often the whole answer: a passage that applies only to non-US filing regimes is actively misleading if it’s returned for a question about IRS Form 1099 (an information return for reporting payments). To fix this, we used the knowledge base’s custom transformation hook to run a POST_CHUNKING Lambda function that prepends each chunk with its document’s H1 title and lead paragraph, which usually states where the content applies. The prefix is capped at roughly 128 tokens (80 characters of title and 300 of scope). Because Cohere Embed English v3 accepts up to 512 tokens per input, chunk bodies are capped at 384 so the header and body fit within that window together. A production probe found about 28 percent of our chunks sat in the 385–512 band and would have had their tails silently truncated. This was the highest-impact retrieval change we made: chunks now carry their own scope into the vector index, instead of it living only in the document’s first chunk. Two practical notes: First, Amazon Bedrock requires the transformation’s intermediate storage to be a separate bucket from the data source bucket. A distinct prefix on the same bucket is rejected. Second, enabling a custom transformation on an existing data source forces a replacement, so plan for a full re-ingestion rather than an in-place change. Retrieval At query time the pipeline over-fetches and then prunes:
question ─► vector search (75 candidates) ─► Cohere Rerank 3.5, server-side in the same Retrieve call ─► top 12 reranked ─► cap of 2 chunks per source document ─► top 5 passed to the model
The reranker runs inside Amazon Bedrock as part of the same Retrieve call, so there is no extra service hop. We keep the 75-candidate pool wide because authoritative articles routinely sit at vector rank 20–50 and only rerank to the top after they’re in the pool. The per-document cap keeps one heavily chunked page from filling every slot. Citation eligibility is enforced by source type in code rather than by prompt instruction. Only the three published sources are citable, because only their URLs resolve to something a customer can open. Code-derived and curated content grounds answers, but doesn’t produce a link the customer can’t follow. Safety and data handling Three boundaries keep one tenant’s data out of another tenant’s session:
The knowledge base holds no tenant-specific content: only published documentation, code-derived product reference, and curated articles. The entitlement and role-check tools take the caller’s organization and email from the service that already authenticated them, so the model can’t widen that scope. AgentCore runtime isolates each session, and conversation history is partitioned by memory, session, and actor ID. That actor ID must come from the calling service rather than from AWS caller identity, because the runtime executes under a single service role. An inferred identity would put every user’s history in one partition.
Amazon Bedrock Guardrails, which provides configurable safeguards based on your application requirements, screens every incoming message before the agent runs. We apply it as a standalone ApplyGuardrail call scoped to the current user turn, which avoids rescanning the entire conversation history on every turn. The PII policy is tuned for tax data. Secrets that have no business flowing through a language model, such as passwords, card verification codes, and cloud access keys, are blocked outright. Numeric identifiers with narrow formats, including Social Security numbers, Individual Taxpayer Identification Numbers (ITINs), bank account and routing numbers, and International Bank Account Numbers (IBANs), are anonymized in place. This lets the agent help with the workflow without ever seeing the value. Credentials for external integrations live in AWS Secrets Manager and are fetched at runtime, never baked into images or configuration. Measuring quality on live traffic The habit that has paid off most is measuring quality continuously in production, without ever blocking a response. The following diagram illustrates how the trace feed fans out to four independent consumers and how an expert’s correction finds its way back into retrieval.
Figure 3: Evaluation flow where CloudWatch traces fan out to online evaluations, a quality judge, a tax-advice classifier, and human review, with approved corrections feeding back into the knowledge base
AgentCore online evaluations sample 10 percent of live sessions from CloudWatch traces and score them with six built-in LLM-as-a-judge evaluators: helpfulness, harmfulness, coherence, instruction following, tool-selection accuracy, and tool-parameter accuracy. Results land in CloudWatch as metrics and per-session scores, so a quality regression shows up on a dashboard rather than in a customer complaint. We layer our own judges on top, reading the same trace feed through a CloudWatch subscription filter. A Lambda function grades each sampled answer on faithfulness to the retrieved sources and relevance of the retrieved articles, and emits the results as CloudWatch metrics. We keep faithfulness and relevance separate because an answer can be faithful to sources that should never have been retrieved. When that happens, the problem is in the retrieval pipeline, not the model. A foundation model classifier checks every response for tax-advice drift. The line between product documentation and tax advice is too fine for a topic filter: “Transferring between your own wallets isn’t a taxable event” is advice, while explaining how Taxbit applies FIFO (First In, First Out) is product documentation. A model prompted with instructions and examples reaches near-zero false positives, compared with roughly 25 percent for a topic filter. Neither classifier adds latency. Humans close the loop. Sampled answers, with personal details scrubbed from each question and answer, go to an internal review channel where subject-matter experts can reply with a correction. Approved corrections are written into the knowledge base’s curated prefix and trigger an incremental ingestion job, so an expert’s fix reaches the next user’s answer within minutes, without a deployment. Deployment and operations The entire stack is defined in AWS Cloud Development Kit (AWS CDK), so standing up a new environment, or a new Region with different residency requirements, is a configuration change. Every pull request runs an offline evaluation suite: a golden set of scenarios judged against expected tool paths and behavior, so prompt and retrieval changes get measured before they ship. The suite also runs nightly against production. Merges deploy to staging first, then to production behind a manual approval gate. Results and impact Taxbit Assist has been in production in the US and the EU since May 2026, with EU traffic served by in-geography inference. Answers are grounded in the curated knowledge base and cited to its sources, and the assistant checks feature availability and the user’s permissions before recommending a workflow. For an embedded support surface, repeat usage is the metric the team watches most closely. One early example stands out. A new client integrating with Taxbit to collect tax documentation (W-8 and W-9 forms, the IRS tax withholding and identification forms) leaned on the assistant heavily during their build. Integration questions that would previously have landed in a shared channel with our team or a support ticket were answered on the spot. The client kept their integration moving without waiting on Taxbit’s support team, and the support team never saw the traffic. Model cost averages under 20 cents per conversation. Prompt caching does much of that work: about three-quarters of input tokens are served from cache, which cuts model cost by more than half. What we would do differently
Scope the corpus before tuning prompts. After we narrowed the index to support and documentation content and gave every chunk its document’s scope, answers improved more than they had from any prompt revision. Measure guardrail filter strength against your own traffic. We measured the Amazon Bedrock Guardrails PII detectors against our own traffic and set the PIN and bank-routing detectors to detect-only, so numeric form identifiers such as 1099 pass through while the detectors still flag genuine sensitive values. Keep the system prompt byte-stable so prompt caching works across users. Bind identity in code from the first prototype. Our early test build had the model pass identity to the tools as an argument. We moved it to the calling service before launch so an injected prompt can’t widen its own access.
What’s next Today, the assistant answers from product knowledge. The next step is an assistant that can answer questions like “How many of my payees are missing tax documentation?” by querying the customer’s own reporting data through the same identity-bound, permission-checked tool pattern. The user asks the question and the model decides which tool and filters to use, but the authenticated caller determines whose data that tool can read, so the model can’t change it. Conclusion Amazon Bedrock AgentCore let a small team ship a cited, permission-aware assistant to regulated enterprise customers in two geographies without operating our own infrastructure for orchestration, vector search, content safety, or evaluation. That freed us to spend our time where it mattered: the corpus, the retrieval pipeline, and what counts as a good answer in tax information reporting. To learn more, see Amazon Bedrock AgentCore, Amazon Bedrock Knowledge Bases, Amazon Bedrock Guardrails, and the Strands Agents SDK on GitHub. If you have questions or want to share how you are solving similar problems, leave a comment.
About the authors
Attribution & Original Source
Synthesized and verified from AWS Machine Learning Blog. All copyrights and intellectual property belong to the original publication.