AssemblyAI optimizes speech inference costs on AWS using EC2 Spot instances
Executive Briefing
“Speech transcription platform AssemblyAI achieved a 70 percent reduction in compute costs...”
Key Takeaways
- 1.The system combines Spot and On-Demand instances on Amazon ECS to run thousands of GPU instances serving speech transcription models.
- 2.The architecture diversifies across multiple GPU instance families including g4dn, g5, and g6 to expand capacity supply and minimize interruption rates.
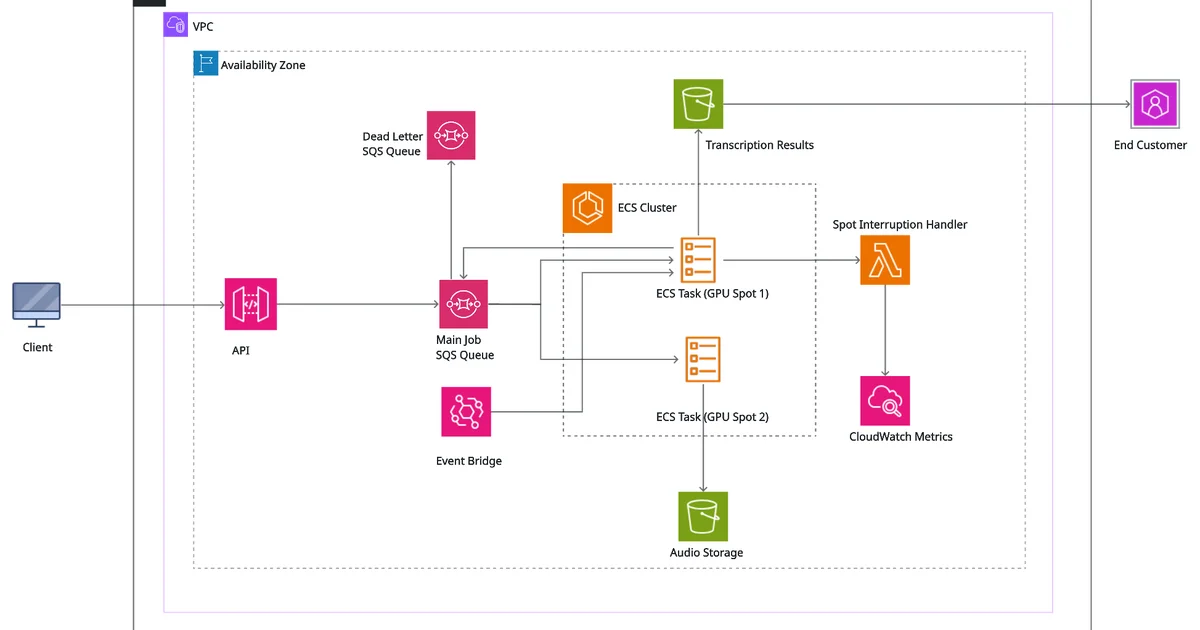
- 3.An Amazon SQS queue architecture and event handler automatically return in-flight tasks to the queue when Spot instances are reclaimed.
- 4.This solution saves the company 70 percent in compute costs compared to relying exclusively on standard On-Demand instances.
Speech transcription platform AssemblyAI achieved a 70 percent reduction in compute costs by integrating Amazon EC2 Spot instances with ECS orchestration.
Key Developments and Technical Context
The system combines Spot and On-Demand instances on Amazon ECS to run thousands of GPU instances serving speech transcription models.
The architecture diversifies across multiple GPU instance families including g4dn, g5, and g6 to expand capacity supply and minimize interruption rates.
An Amazon SQS queue architecture and event handler automatically return in-flight tasks to the queue when Spot instances are reclaimed.
This solution saves the company 70 percent in compute costs compared to relying exclusively on standard On-Demand instances.
Strategic Analysis and Industry Implications
Spreading risk across different GPU families helps the system maintain stability even when one hardware line experiences supply pressure.
Decoupling job submission from actual execution establishes a robust foundation for handling sudden server reclamations gracefully.
Outlook and Key Factors to Watch
The documentation does not provide specific metrics on the percentage of tasks routed to dead letter queues after exhausting retry attempts.
The precise average processing duration for specific audio files under heavy concurrent loads is not detailed.