Amazon SageMaker HyperPod adds NVIDIA Dynamo support for large model inference
Executive Briefing
“Amazon SageMaker HyperPod Inference now integrates NVIDIA Dynamo to simplify multi-node...”
Key Takeaways
- 1.Amazon SageMaker HyperPod Inference supports NVIDIA Dynamo, combining Dynamo's distributed inference capabilities with HyperPod infrastructure management.
- 2.Dynamo is an open source distributed inference framework supporting multi-node deployment, disaggregated prefill and decode, and KV-aware routing with engines like vLLM, SGLang, and TensorRT-LLM.
- 3.In benchmarks using Qwen3-235B across two p5en.48xlarge instances, disaggregated serving achieved 2.05 times the highest throughput of aggregated serving.
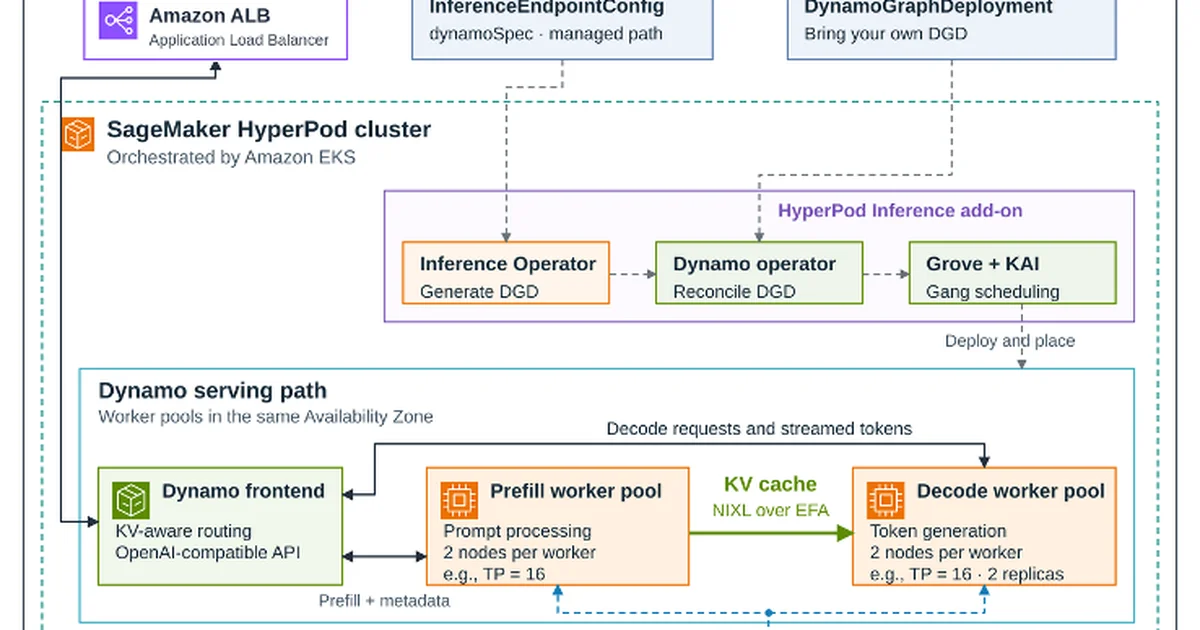
Amazon SageMaker HyperPod Inference now integrates NVIDIA Dynamo to simplify multi-node large language model deployments. The platform combines distributed inference, disaggregated prefill and decode stages, and KV-aware routing.
Key Developments & Primary Facts
Amazon SageMaker HyperPod Inference supports NVIDIA Dynamo, combining Dynamo's distributed inference capabilities with HyperPod infrastructure management.
Dynamo is an open source distributed inference framework supporting multi-node deployment, disaggregated prefill and decode, and KV-aware routing with engines like vLLM, SGLang, and TensorRT-LLM.
In benchmarks using Qwen3-235B across two p5en.48xlarge instances, disaggregated serving achieved 2.05 times the highest throughput of aggregated serving.
Strategic Analysis & Implications
Disaggregating prefill and decode stages allows engineering teams to tune GPU worker pools independently and mitigate bottlenecks caused by long input prompts.
High-performance networking and automated node replacement from HyperPod help maintain cluster stability for large-scale AI serving infrastructure.
Outlook & Factors to Watch
The exact performance characteristics on alternative proprietary model architectures or different hardware generations remain unmeasured in this scope.