Amazon SageMaker AI automatically detects latency and idle GPUs
Executive Briefing
“Amazon SageMaker AI introduces automated monitoring for generative AI inference endpoints...”
Key Takeaways
- 1.The system monitors inference endpoints using vLLM serving containers and GPU instances by default with no setup required.
- 2.The tool evaluates operational signals including latency, GPU utilization, and serving configuration without reading request or response content.
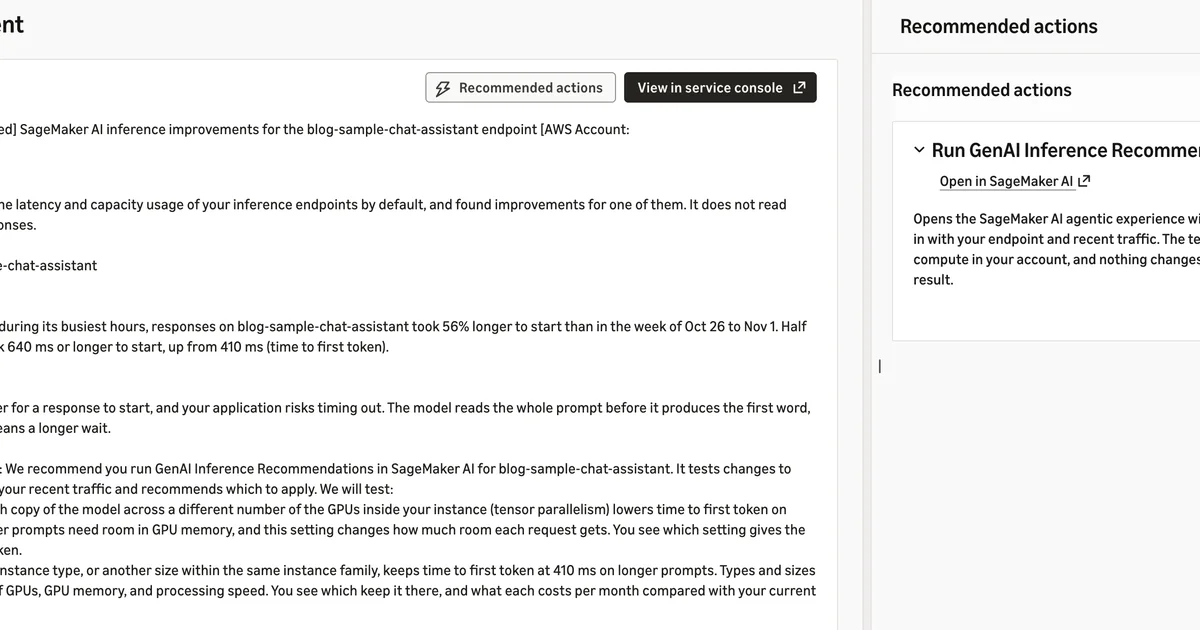
- 3.When findings occur, the service sends notifications via AWS Health with links to open an agentic experience in Amazon SageMaker Studio for benchmarking.
Amazon SageMaker AI introduces automated monitoring for generative AI inference endpoints to surface latency drift, unused hardware, and missed configuration optimizations. The system operates on operational telemetry without inspecting user request or response data.
Key Developments & Primary Facts
The system monitors inference endpoints using vLLM serving containers and GPU instances by default with no setup required.
The tool evaluates operational signals including latency, GPU utilization, and serving configuration without reading request or response content.
When findings occur, the service sends notifications via AWS Health with links to open an agentic experience in Amazon SageMaker Studio for benchmarking.
Strategic Analysis & Implications
Shifting optimization from manual point-in-time snapshots to continuous automated observation helps engineering teams maintain model efficiency as workloads and prompt lengths evolve.
Ished benchmarking on separate compute resources mitigates production risks by allowing teams to evaluate alternative configurations safely before making changes.
Outlook & Factors to Watch
Detailed data regarding exact operational costs and compute consumption for large-scale benchmark jobs remains to be fully quantified in practice.