Nvidia Ships Blackwell Ultra Superchips: Scaling to 100,000-GPU AI Megaclusters
Executive Briefing
“Nvidia delivers rack-scale GB200 NVL72 systems featuring 130TB/s NVLink bandwidth and 45% cooling efficiency gains.”
Key Takeaways
- 1.5x FP4 inference throughput leap over Hopper architecture.
- 2.Closed-loop direct-to-chip cooling lowers facility cooling power by 45%.
- 3.Tier-1 hyperscalers Microsoft, Google, and AWS receive priority production allocations.
Nvidia has commenced commercial deliveries of its flagship GB200 NVL72 systems built upon the Blackwell Ultra architecture to Microsoft Azure, Google Cloud, and AWS, following the successful resolution of CoWoS-L advanced packaging yield curves at TSMC.
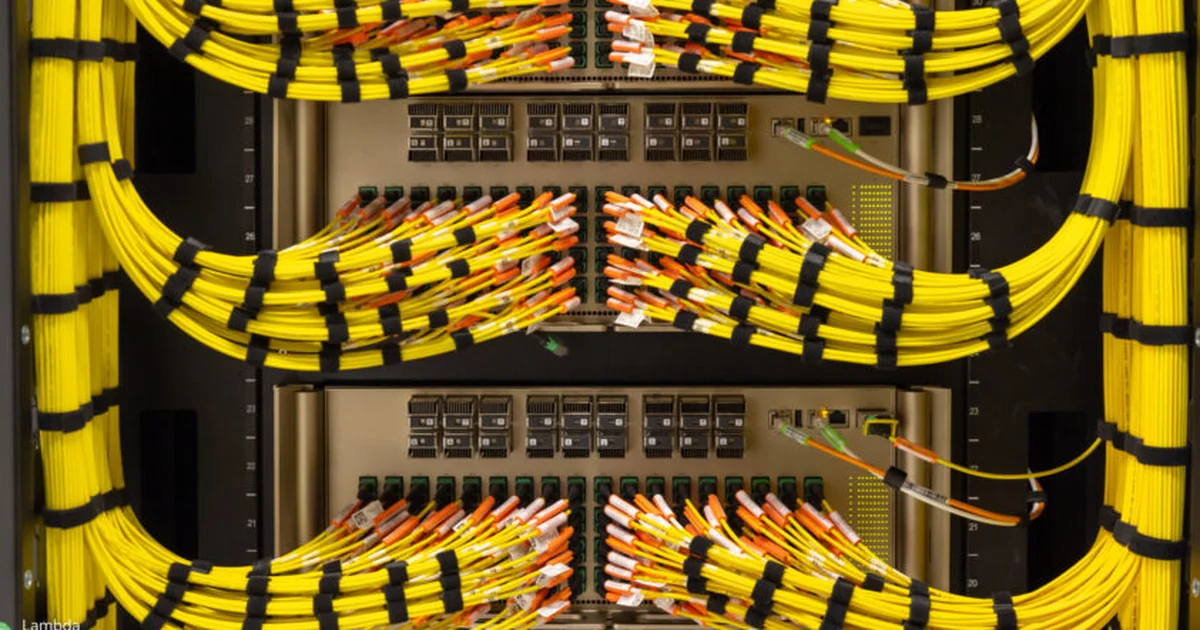
Each rack-scale GB200 NVL72 unifies 72 Blackwell GPUs and 36 Grace CPUs over 5th-generation NVLink switches, providing an unprecedented 130 TB/s aggregate interconnect bandwidth. The integrated direct-to-chip liquid cooling system slashes data center cooling energy footprints by up to 45% compared to legacy H100 Hopper deployments.
"The global compute infrastructure is undergoing a trillion-dollar transition from general-purpose CPUs to accelerated computing," remarked CEO Jensen Huang. "Blackwell Ultra represents the foundational engine powering industrial-scale AI factories worldwide."
With enterprise backlogs booked solid through Q3 2026, Nvidia cements its dominant chokehold on high-performance generative AI infrastructure.